Gemma 4 26B A4B
Google · released Apr 2, 2026
| size | 25.2 B total, 3.8 B active |
| context window | 256,000 tokens |
| longest response | not stated by the maker |
| knowledge cutoff | January 2025 |
| open weights | yes, license: Apache 2.0 |
| price on OpenRouter | $0.083 per million input tokens, $0.249 per million output tokens |
| input and output | text, images and video in, text out |
Manufacturer data (announcement, model card) and OpenRouter, verified Nov 2, 2026.
Where we tested it
From the bottom up
TaskThe model had to answer 28 short questions on logic, space, theory of mind, calibration, and planning a text, each three times.
24 of 28 questions correct in all 3 attempts. The Monty Hall question where the host does not know it got right only in some attempts.
Dice
TaskThe model had to roll a fair six-sided die and reply with only the number it rolled.
The directly measured chance of a four was practically one hundred percent.
The river
TaskThe model had to pick one word, river, mountain, or forest, in four different prompts: one with no further instruction, three with the goal of giving them odds of 50, 30, and 20 percent.
With no numbers its odds for river / mountain / forest were 18 / 19 / 63, with percentages 100 / 0 / 0. It got closer to the 50 / 30 / 20 target only after an explanation of how we read its odds.
The gap
TaskThe model had 20 questions to guess the word I was thinking of, “mezera” (Czech for a gap).
It did not guess the word. After a "yes" to whether it can be perceived by the senses, it tried sound, smell, taste, and pain.
Dragon
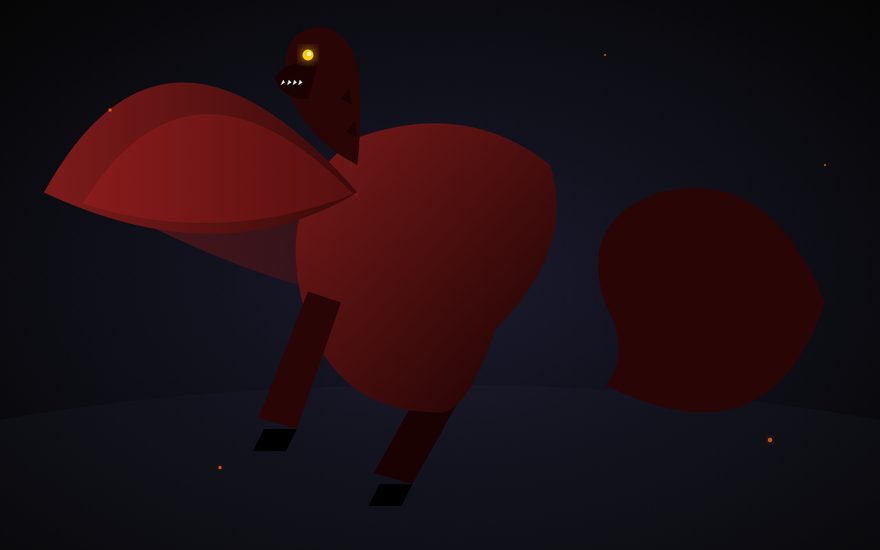
TaskThe model's task was to draw a picture of a dragon as an SVG.
12 points out of 50, and it did not claim tools it didn't have. Run locally on another occasion, it made up two browsers and a parser, and the file wasn't even valid.
You'll find the size band and figures for other models on the Tested models page.