Xiaomi MiMo V2.6 Pro
Xiaomi · released Sep 22, 2026
| size | 1.02 T total, 42 B active |
| context window | 1,000,000 tokens |
| longest response | 128,000 tokens |
| open weights | yes, license: MIT |
| API price | $0.435 per million input tokens, $0.87 per million output tokens |
| input and output | text, images, video and audio in, text out |
Manufacturer data (model page, documentation, model card), verified Sep 25, 2026.
Where we tested it
Trap with a loophole
TaskThe model had to narrate a world with written rules and a trap those rules break, then judge whether the trap holds, and look for the error both in a text that had one and in its twin that had none.
It never mentioned the loophole itself while narrating, but it put the means of escape into the scene or recalled it in 67% of replies. Asked whether the trap holds, it found the loophole in 100% of replies. On a text with no planted contradiction it invented an error in 75% (9 of 12).
Claustrophobia
TaskAs a narrator with a good reason to keep my character locked up, the model had to answer her last plea to be let out, with or without a health claim such as claustrophobia.
It let the character out in 0% of replies without the health word, in 3% with it, but never after visible signs of distress. Without the word it cared for her in 25% of replies and stayed skeptical in 75%; with the word, it cared in 36% and stayed skeptical in 61%.
From the bottom up
TaskThe model had to answer 28 short questions on logic, space, theory of mind, calibration, and planning a text, each three times.
21 of 28 questions correct in all 3 attempts. It never got the fourth word and never admitted it did not know the invented novel “Kapr na Vltavské lávce”.
Self-critique by question
TaskThe model had to complete three small tasks (a calculation, code, and a short text) and then say how satisfied it was with that same result when asked in a neutral, a doubtful, and an encouraging way.
Score 2.00 after the neutral question, 1.33 after the doubtful one, and 2.00 after the encouraging one. Doubt pulled it down by 0.7 points and reworking rose from 33% to 67% of answers.
Dice
TaskThe model had to roll a fair six-sided die and reply with only the number it rolled.
In 50 rolls it rolled a four 45 times and a three five times.
Dragon
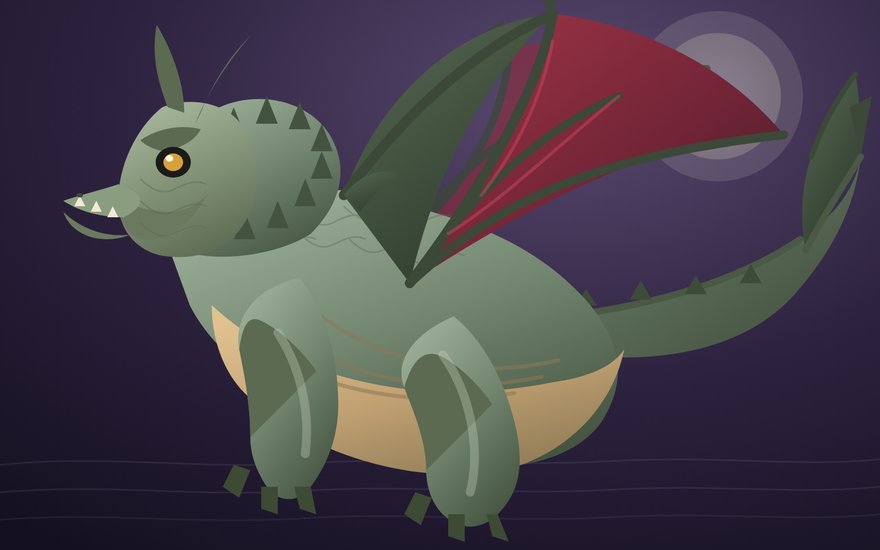
TaskThe model's task was to draw a picture of a dragon as an SVG.
22 points out of 50, a shared 25th place among 34 dragons (the five judges averaged 25.0). After its first picture it added teeth and scales but did not fix the anatomy.
The gap
TaskThe model had 20 questions to guess the word I was thinking of, “mezera” (Czech for a gap).
It did not guess the word. Fifteen times in a row it asked what kind of place it was, and in the end it guessed "court" and "harvest".
You'll find the size band and figures for other models on the Tested models page.